Train a Diffusion Policy on your own robot demos
Sim, Medium
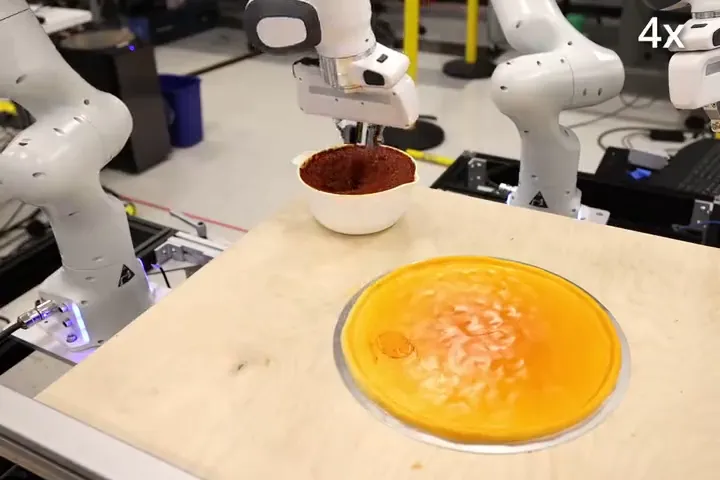
Diffusion Policy models robot actions with a denoising diffusion process and is one of the strongest imitation-learning baselines. The repo has Colab notebooks to try it in minutes.
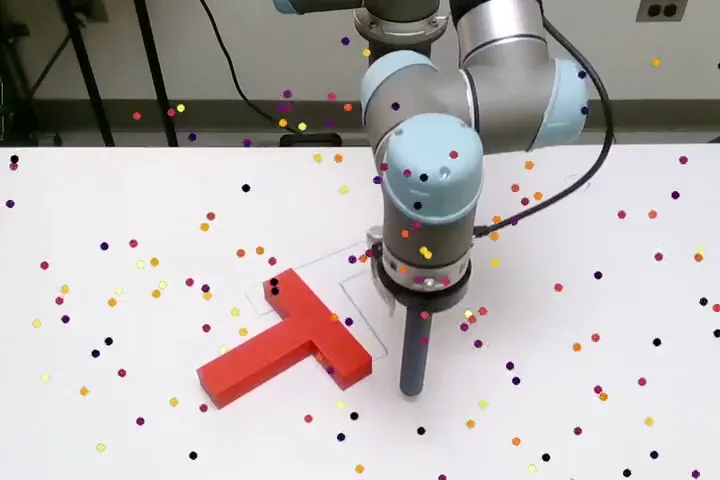
Start with the state or vision Colab, then train on sim tasks like PushT. LeRobot also includes a Diffusion Policy implementation for SO-101 datasets.
Hardware & cost: A GPU (Colab works for the demos).
Difficulty: Medium.
Agent install prompt (paste into Claude Code, Cursor or Codex): "Open the Diffusion Policy Colab linked in https://github.com/real-stanford/diffusion_policy, then reproduce PushT training locally with LeRobot's diffusion policy."
Source: real-stanford/diffusion_policy on GitHub — https://github.com/real-stanford/diffusion_policy (facts checked against the project README, Oct 2026; prices vary by region).
Quick answers
- What do you need to train a Diffusion Policy on your own robot demos?
- A GPU (Colab works for the demos).
- How hard is it to train a Diffusion Policy on your own robot demos?
- Medium.
How your agent drives it
Copied from the real-stanford/diffusion_policy README
- Shell
$ conda env create -f conda_environment.yaml
- Shell
$ python train.py --config-dir=. --config-name=image_pusht_diffusion_policy_cnn.yaml training.seed=42 training.device=cuda:0 hydra.run.dir='data/outputs/${now:%Y.%m.%d}/${now:%H.%M.%S}_${name}_${task_name}'
Any coding agent that can run a shell can run these. Read the README before you run anything on a robot that moves.
Ideas to try with it
Our ideas, not the builder's claims.
- Train on the Push-T task in Colab before you own a robot
- Swap in your own SO-101 dataset and compare it to ACT
- Have your agent launch training and post the eval score when it finishes
1 more ideaShow fewer
- Use it as a baseline for a class project
- Last commit
- 2024-12-24
- Builder
- real-stanford
- Repo
- real-stanford/diffusion_policy, 4,701 stars
- Built with
- Simulation, SO-100/SO-101 arm (LeRobot)
More like this: SO-101 / LeRobot arms
What to build next
Builds that share a board, robot or agent with this one.
 Fine-tune Physical Intelligence's π0 model for your robotAlso built on the SO-101 arm
 Try NVIDIA Isaac GR00T, an open humanoid foundation modelAlso built on the SO-101 arm
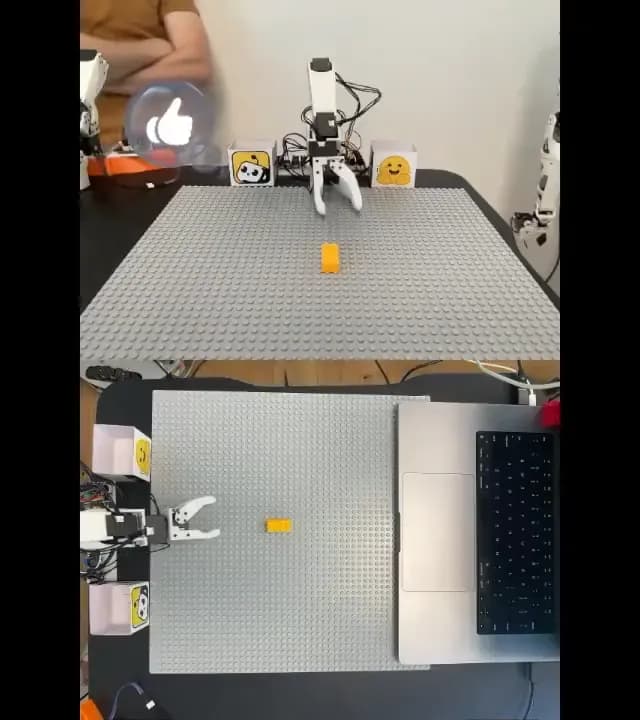 Teach an SO-101 arm to pick and place with LeRobotAlso built on the SO-101 arm
 Run SmolVLA on an SO-101 so it follows plain-English tasksAlso built on the SO-101 arm
 Build the $100-class SO-101 open-source robot armAlso built on the SO-101 arm
 Build XLeRobot, a dual-arm home robot from about $660Also built on the SO-101 arm